Continuous and Discontinuous Development: Read a Learning Curve
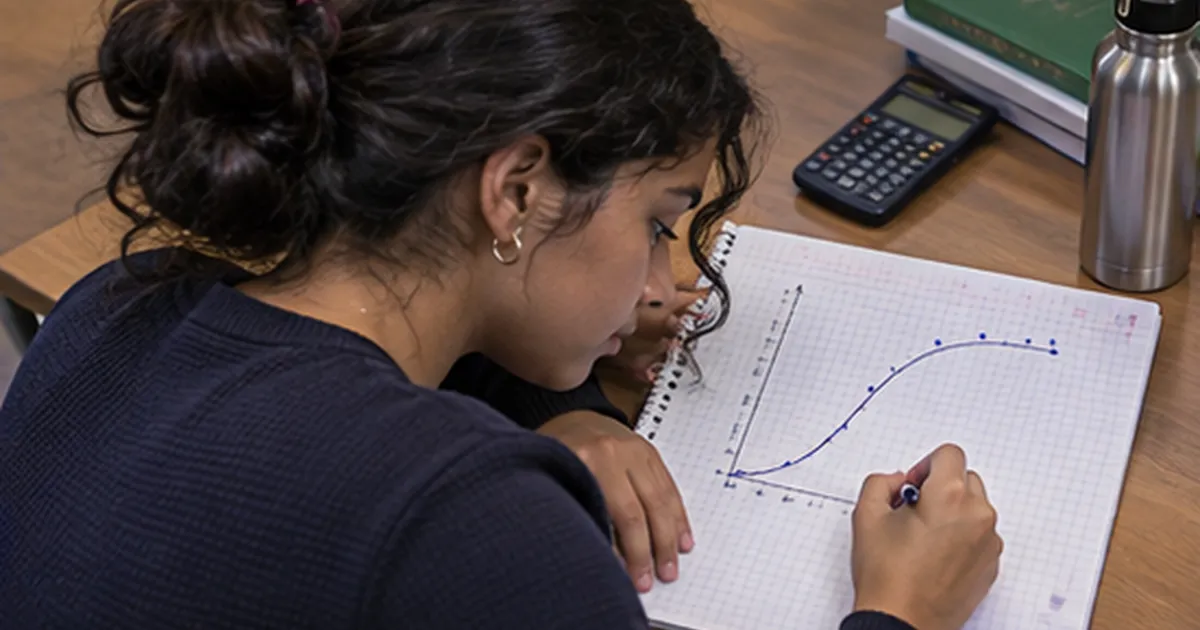
In a quiet college library, Maya reviewed her weekly word counts from a semester-long writing project. From Week 1 to Week 6, her output climbed steadily: 1,200, 1,350, 1,500, 1,650, 1,800, and 1,950 words per week—a smooth, linear increase suggesting continuous development. But in Week 7, she switched strategies: she began outlining each essay before drafting. Her output jumped to 2,400 words. By Week 8, it reached 2,700. The curve now appeared to leap upward—discontinuous. Was her growth truly sudden, or did the strategy shift merely reveal a latent capacity? And if another student showed a similar jump without a documented strategy change, could we assume the same cause? This puzzle illustrates a core challenge in interpreting learning curves: distinguishing real developmental shifts from artifacts of measurement, timing, and sampling.
Try the distinction with vocabulary
Imagine a child uses 20 distinct words in a sample one week and 24 in a comparable sample the next. That difference describes a change in the count. Now look at how the child uses the words. Pairing two familiar words to make a new request could change the organization of communication without adding a single word to the count. Conversely, four new object names could raise the count while the child continues to use one word at a time. Decide which outcome your graph represents before giving its shape a developmental interpretation.
Tracking Growth: The Weekly Word Count
Maya’s project required eight weekly submissions. Her initial approach was reactive: she read the prompt, brainstormed briefly, and wrote directly. The steady rise in word count—increasing by 150 words each week—suggested gradual improvement in fluency or confidence. This pattern fits a model of continuous development, where growth occurs incrementally over time. The consistent slope implies that each week built on the last, with no abrupt changes in capability.
But in Week 7, Maya adopted a new strategy: structured outlining. She began each assignment by drafting a detailed skeleton of arguments and evidence before writing. This change coincided with a 450-word jump—from 1,950 to 2,400—and another 300-word gain the following week. The learning curve now showed a sharp upward inflection, resembling discontinuous development, where progress appears to leap rather than creep.
At first glance, the data suggest a threshold was crossed—a sudden gain in skill or efficiency. But does the shape of the curve alone prove a qualitative shift in ability? Or could the change reflect a shift in method, not mind?
Sampling and the Shape of Progress
The apparent discontinuity in Maya’s curve depends heavily on when and how often data were collected. Had measurements occurred only once per month, the jump might have been missed entirely. For example, a monthly average would show:
- Month 1 (Weeks 1–4): (1,200 + 1,350 + 1,500 + 1,650) ÷ 4 = 1,425 words
- Month 2 (Weeks 5–8): (1,800 + 1,950 + 2,400 + 2,700) ÷ 4 = 2,212.5 words
This yields an increase of 787.5 words per month—an impressive gain, but one that obscures the timing and nature of the change. The monthly view flattens variation within periods and may falsely suggest steady growth across the entire second month, even though the real shift occurred in Week 7.
Conversely, had data been sampled daily, the curve might show smaller, incremental gains during Week 7 as Maya adjusted to outlining—perhaps revealing a smoother transition. The choice of sampling interval thus directly shapes the perceived continuity of development. Weekly sampling made the shift appear abrupt; daily sampling might have shown it as a rapid but continuous acceleration.
This illustrates a broader principle: the granularity of measurement influences whether development appears continuous or discontinuous. Sparse sampling can create the illusion of jumps, while denser sampling may reveal underlying trends.
Longitudinal vs. Cross-Sectional Views
Maya’s data are longitudinal: repeated measures from one individual over time. This allows tracking of individual change and the timing of strategy shifts. But suppose instead we compared different students at different stages. A cross-sectional study might survey eight students—one in each week of their writing development—with each submitting a single essay.
Imagine the following illustrative data:
- Week 1: average 1,200 words
- Week 2: 1,350
- Week 3: 1,500
- Week 4: 1,650
- Week 5: 1,800
- Week 6: 1,950
- Week 7: 2,400
- Week 8: 2,700
This cross-sectional curve looks identical to Maya’s longitudinal one. But it carries a critical limitation: differences between groups could reflect cohort effects rather than development. For example, students in Week 7 might have been assigned easier prompts, or they might have been from a different program with more writing practice. In contrast, Maya’s data rule out such confounds—her improvement occurred within the same context, with the same prompts, before and after a documented change.
Thus, while cross-sectional data can suggest developmental trends, they cannot confirm individual growth or pinpoint causes. Only longitudinal data can link a strategy shift to a change in output for the same person.
Age, Cohort, and the Timing of Change
In developmental research, age is often used as a proxy for time, but it conflates individual progression with generational differences. In Maya’s case, time is measured in weeks of a project, not years of life. But the principle is similar: a jump at Week 7 reflects a change in her experience (strategy adoption), not an inevitable milestone.
Suppose a cross-sectional study compared students in different years of college, finding that seniors write 30% more than freshmen. One might infer continuous development across college years. But if seniors also took more writing-intensive courses, the difference might reflect opportunity, not maturation. Similarly, Maya’s jump was not age-related but experience-related: her exposure to a new method.
This distinction matters. In workplace training, an employee’s improved performance after a workshop might reflect learning, not aging. Confusing cohort with development leads to false assumptions about when and why change occurs.
Performance vs. Trait: What Are We Measuring?
Maya’s word count is a measure of performance—what she produced under specific conditions. It is not a direct measure of a stable trait, such as writing ability or cognitive capacity. Performance fluctuates with strategy, motivation, task design, and context.
Had Maya’s instructor interpreted her Week 7 jump as evidence of a new developmental stage in writing fluency, they might have concluded she had reached a higher level of competence. But if, in Week 9, she reverted to her old method and output dropped to 2,000 words, that would challenge the idea of a permanent shift. Instead, performance responded to strategy.
This highlights a key point: observed performance changes do not necessarily reflect changes in underlying traits. A student’s improved test score after learning a test-taking strategy may not mean they understand more—just that they can navigate the format better. Similarly, Maya’s increased output may reflect efficiency gains from outlining, not an increase in vocabulary or idea generation.
What the Data Can and Cannot Show
Maya’s weekly data show a clear association between her strategy shift and increased output. But association is not causation. Could the jump have occurred for other reasons? Perhaps she became more motivated, had more time, or received encouraging feedback. The timeline suggests the strategy change was pivotal, but the data alone cannot prove it.
Consider an alternative interpretation: Maya’s increase began in Week 6, when she started reading more sources. The outlining in Week 7 was a symptom of growing confidence, not its cause. Or perhaps the jump was due to reduced anxiety after receiving positive feedback on Week 6’s submission. Without controlled conditions, multiple explanations remain plausible.
Moreover, the shape of the curve depends on what is measured. If we tracked revision time instead of word count, the pattern might differ. Suppose Maya spent more time revising in Weeks 1–6 but less in Weeks 7–8 due to better initial organization. Then, total effort might have been stable, even as output rose. The learning curve would still show discontinuous growth in output, but not in total work.
Thus, the apparent nature of development—continuous or discontinuous—depends on the choice of metric, the timing of measurement, and the presence of unmeasured variables.
Transfer: From Writing to Workplace Learning
Consider an illustrative workplace scenario. Alex, a customer service representative, handled an average of 25 calls per day over six weeks. In Week 7, his company introduced a new script and knowledge base. His daily call volume jumped to 35 in Week 7 and 38 in Week 8.
Like Maya, Alex shows a discontinuous jump in performance. But is this due to a sudden increase in skill, or a change in tools? The script reduced decision time; the knowledge base made answers easier to find. His trait—problem-solving speed—may not have changed, but his performance did.
If the company sampled only monthly, they might see:
- Month 1 (Weeks 1–4): (25 + 25 + 25 + 25) ÷ 4 = 25 calls/day
- Month 2 (Weeks 5–8): (25 + 25 + 35 + 38) ÷ 4 = 30.75 calls/day
This suggests gradual improvement. But weekly data reveal a sharp shift, aligning with the intervention. Without knowing about the new tools, an observer might assume Alex matured into the role. But the real change was environmental, not developmental.
This mirrors Maya’s case: a strategy shift, not a maturational threshold, explained the jump. In both cases, the learning curve’s shape depended on when and how data were collected, and what external changes occurred.
Seeing Beyond the Curve
The distinction between continuous and discontinuous development is not always in the learner—but in the lens of measurement. Maya’s curve appeared discontinuous because of weekly sampling and a timed strategy shift. With daily data, it might have looked continuous. In a cross-sectional study, the same pattern might have been misattributed to age or cohort.
Performance metrics like word count or call volume are sensitive to context. They reflect not just ability but strategy, support, and task structure. A jump in output may signal a change in method, not a leap in trait.
For educators and learners, this means interpreting progress with care. A sudden improvement may be cause for celebration—but also for inquiry. Was it a new insight? A better tool? More practice? The shape of the curve hints at the story, but only context reveals the cause.
In the end, Maya kept outlining. Her average output stayed above 2,500 words. But she also noted that her first drafts required fewer revisions. The strategy didn’t just boost quantity—it improved quality. The curve told part of the story. The rest required reflection.
For the wider context, read Roovet’s guide to developmental psychology across the lifespan or explore the developmental psychology course.